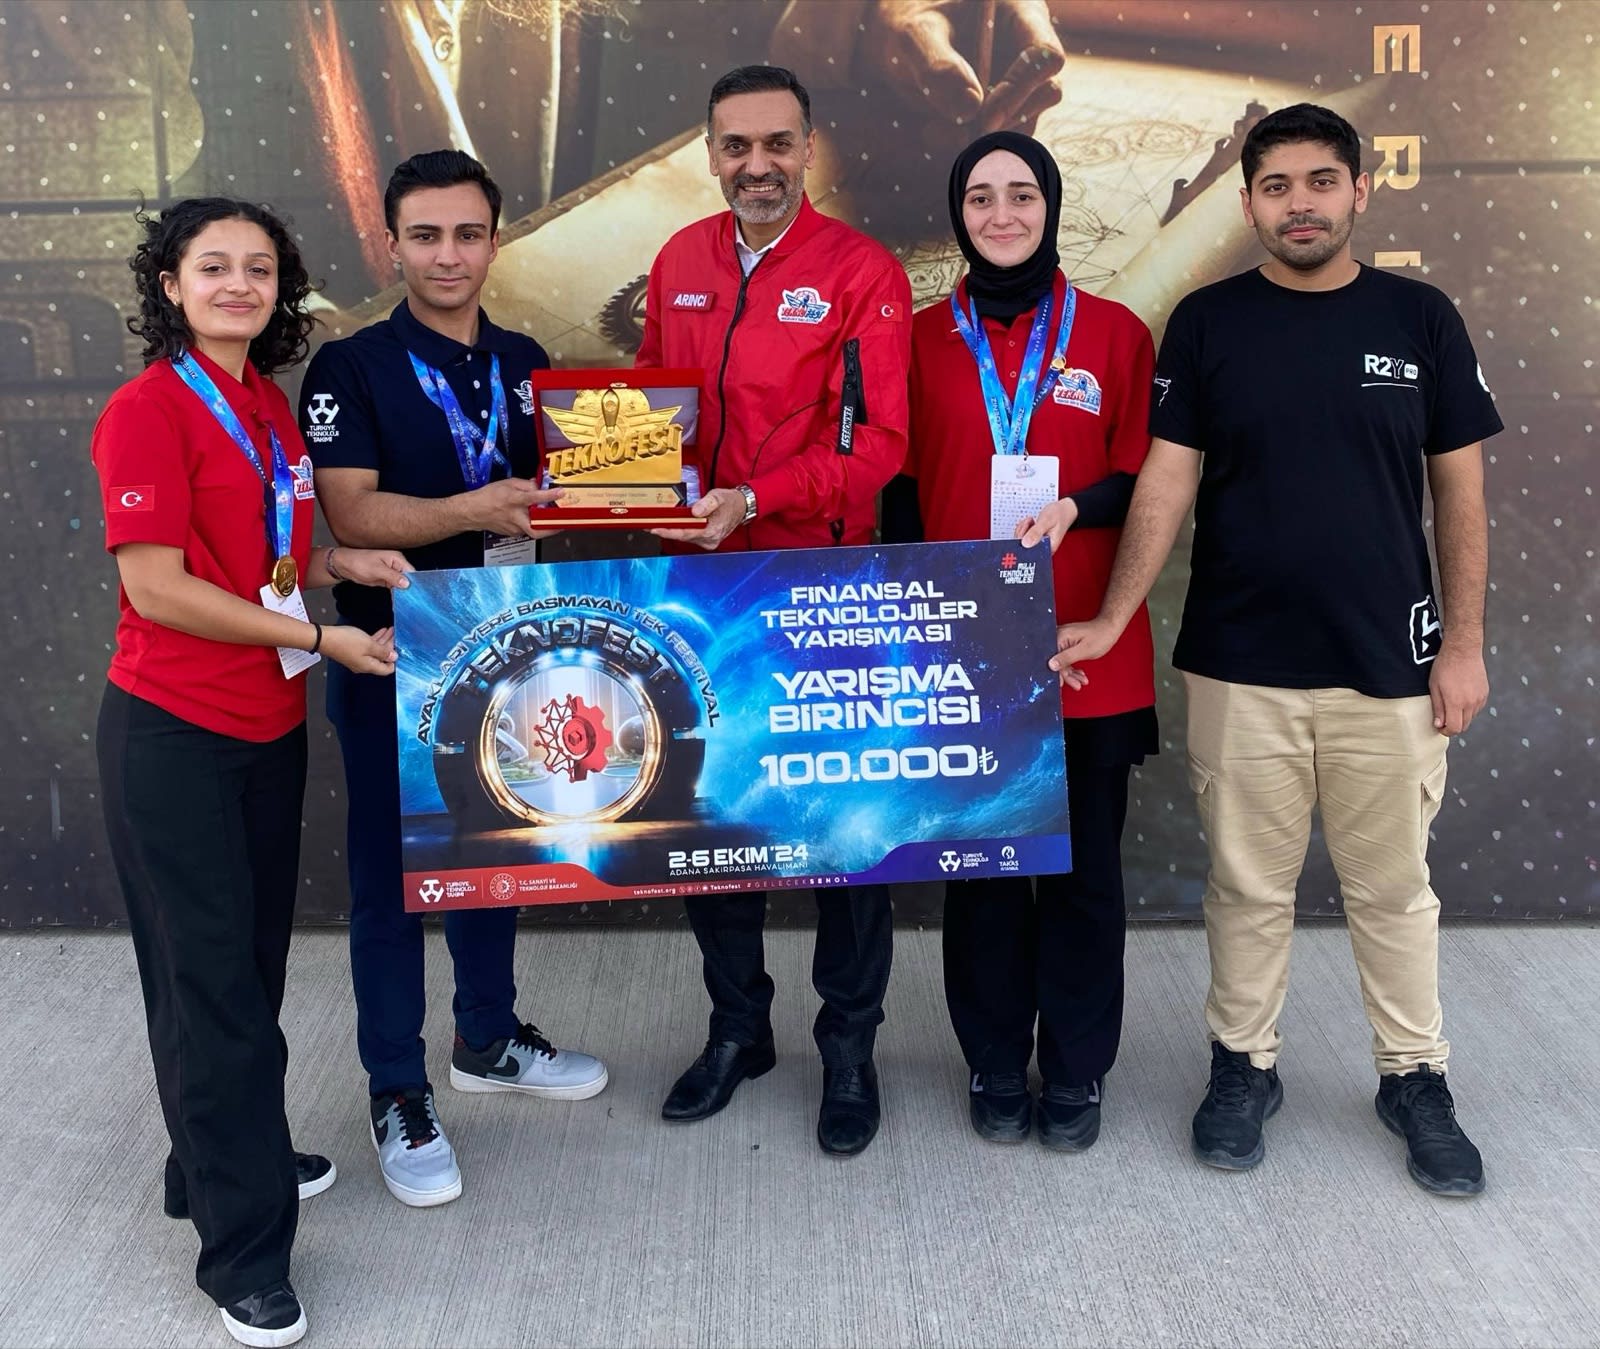
From 2 to 6 October 2024, at Adana Şakirpaşa Airport, we took first place in the undergraduate category of the TEKNOFEST Financial Technologies Competition. Lifting the trophy on stage took a few seconds; behind it was a question we had been working on for months: how do you catch a fraudster who keeps changing disguises?
The problem: fixed rules go stale
Credit card fraud reached 32.34 billion dollars in losses worldwide in 2021. The classic approach at banks is rule-based systems: "anything above this amount is suspicious", "transactions from this country are risky". The trouble is that fraudsters learn these rules too, and keep refining their methods to avoid detection.
As R2Y Fintek, we set ourselves this goal: instead of writing rules by hand, a model that learns the pattern from data and keeps updating itself with new data.
The data: the imbalance trap
We worked with a dataset of 284,807 transactions made by European cardholders. For privacy reasons, most of the features come as 28 components transformed with PCA; there is no readable field like "this transaction happened at night", only numbers.
The real difficulty lies elsewhere: fraudulent transactions make up a tiny share of the dataset. That means:
Even a model that calls every transaction "normal" scores above 99% accuracy. Accuracy on its own tells you nothing.
So when evaluating the model we measured the two classes separately, and focused mainly on precision and recall for the fraud class.
The model: don't trust a single one
We built a hybrid that combines XGBoost with an artificial neural network (ANN). We split the data into training, validation and test sets, and trained the ANN for 300 epochs with the Adam optimiser and cross-entropy loss.
On normal transactions, precision, recall and F1 all stayed at around 99.9%. On the fraud class, the F1 score was 86.8%. In a simulation of 500 transactions picked at random from the test data to mimic a real-world scenario, the model ran at 99.80% accuracy.
The system: from model to product
We didn't present the jury with just a model, but with a pipeline:
- When a transaction comes in, the model calculates a fraud probability.
- Transactions with a probability of 80% or more are flagged as suspicious.
- The trained model is deployed to local servers; local devices run through that server.
- The model is periodically retrained on multi-source data coming through OLAP and redeployed to the servers.
That last step was the original part of the project: as fraud methods change, the model keeps learning the new patterns.
After the stage
After the win, we received a certificate of appreciation from the Governorship of Istanbul. But for me the most lasting gain was this lesson: choosing a good metric comes before choosing a good model. On imbalanced data it's easy to boast about accuracy; knowing which error is more expensive is the real engineering.
I carried this way of thinking into my later work on fund risk scoring at Borsa Istanbul. But that's a topic for another post.